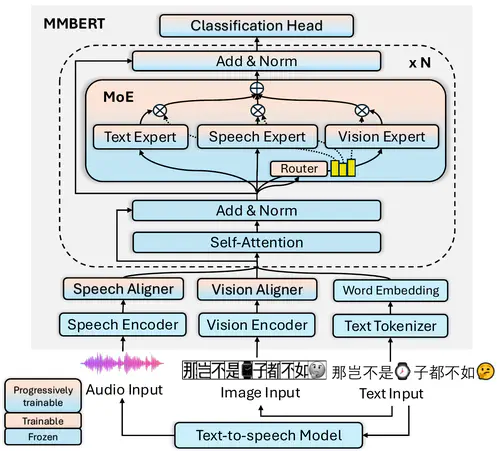
Cloaking techniques such as character deformation, homophonic substitution, abbreviation and code-mixing with pinyin or emojis let hate speech on Chinese social networks evade text-only detectors. MMBERT is a BERT-based multimodal framework that integrates textual, speech and visual modalities through a Mixture-of-Experts architecture, with modality-specific experts, a shared self-attention mechanism and router-based expert allocation. A progressive three-stage training paradigm keeps MoE training stable, and MMBERT significantly surpasses fine-tuned BERT-based encoders, fine-tuned LLMs and in-context learning with LLMs on several Chinese hate speech datasets.